Blackwell
NVIDIA Tensor Core FP32 methods speed up Point Edge Transformer MLIP inference
NVIDIA says Tensor Core methods that emulate FP32 matrix math can speed up machine learning interatomic potentials without retraining. In tests on the Point Edge…
CoreWeave posts 441,740 tokens per second on DeepSeek-R1 in MLPerf Endpoints
CoreWeave says it delivered leading results in the inaugural MLPerf 0.7 Endpoints benchmark, sustaining 441,740 output tokens per second with the DeepSeek-R1 reasoning…
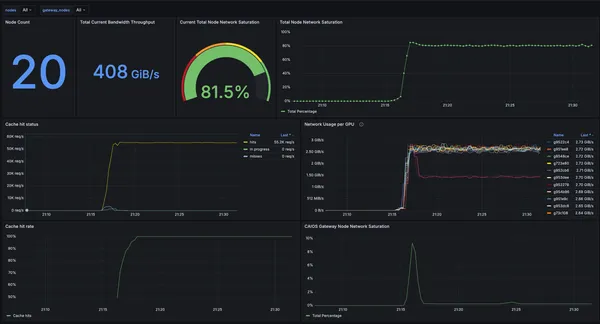
CoreWeave makes AI Object Storage generally available at NVIDIA GTC
CoreWeave has made CoreWeave AI Object Storage generally available, a managed, S3-compatible object storage service built for AI training and inference. The company…
NVIDIA RTX Spark Windows laptops launch from $2,399 with up to 128GB memory
NVIDIA RTX Spark laptops are now available, bringing Blackwell RTX graphics, up to 128GB of unified memory and the NVIDIA AI platform to slim, premium Windows PCs.…
Baseten adds NVIDIA's Nemotron 3.5 Super VL, an open multimodal model
Baseten has made NVIDIA's Nemotron 3.5 Super VL available for inference and customization. The open multimodal model combines visual understanding, reasoning and tool…
NVIDIA Brings Green Contexts to the CUDA Runtime API in CUDA 13.1
NVIDIA has detailed how green contexts, now accessible through the CUDA Runtime API as of CUDA 13.1, let a single application divide GPU execution resources such as SMs…
 Top story
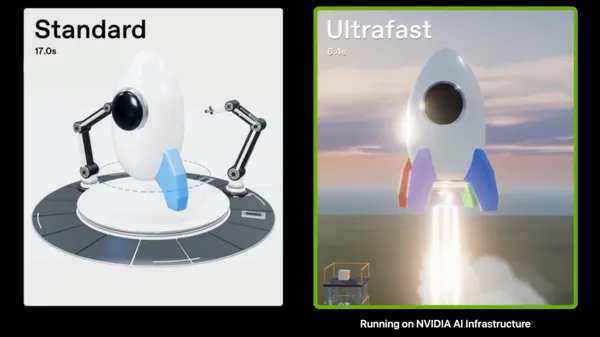
OpenAI's GPT-6 Astra Ultrafast Runs on NVIDIA Blackwell, Up to 8x Faster
GPT-6 Astra Ultrafast, a faster mode of OpenAI's Astra model running on NVIDIA Blackwell GPUs, is available now in the OpenAI API and to eligible ChatGPT Work and Codex…
ResearchMeta's TLX Jagged Flash Attention Beats FA4 on Blackwell With 3x Less Code
Meta's team has built a Jagged Flash Attention (JFA) kernel for NVIDIA Blackwell B200 using TLX (Triton Low-level Extensions). According to the PyTorch blog post, it…