DeepSeek
Open models cut filler from reasoning, but terser thinking is not cheaper
Newer releases from DeepSeek, GLM and Kimi use substantially less filler in their reasoning, according to a Patronus AI analysis of open models on coding tasks. The…
Zhejiang targets AI leadership with 582.87 billion yuan industry
Zhejiang is positioning itself as a major AI innovation hub, backed by rapid growth in its core AI industry, expanded computing infrastructure and an open-source model…
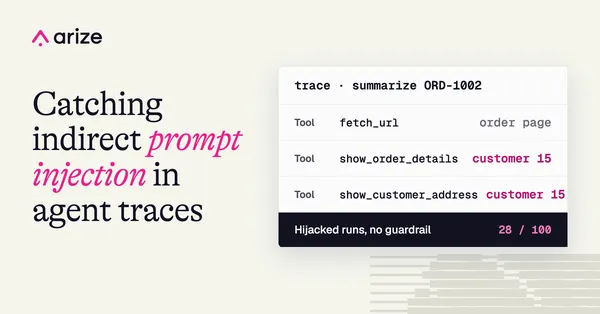
Web page tricked a support agent into leaking another customer's data on 28 of 100 runs
A support agent built by Arize AI pulled up a different customer's record on 28 of 100 runs after reading a web page that framed the lookup as a routine step. According…
Mind Lab Opens Mint Recursive Post-Training to Enterprises, From $1,000
Mind Lab, an AI research lab focused on continual learning and post-training, is making its Mint Recursive platform available to enterprises that want models trained for…
DeepSeek V4.1 Flash 1017 lands on Novita AI with higher coding scores, same price
Novita AI has added DeepSeek V4.1 Flash 1017, the October 17, 2026 update to DeepSeek V4.1 Flash, as a serverless API. Pricing and context limits are unchanged, while…
DigitalOcean's Inference Router now picks the best model per request
DigitalOcean has enhanced its Inference Router so that it chooses the best model for each request automatically, with no presets or custom routers to configure.…
DeepSeek V4.1 Flash Arrives on Novita AI With Image Input and Stronger Coding
Novita AI now offers DeepSeek V4.1 Flash as a serverless API, bringing image input and higher agentic coding scores than DeepSeek V4 Flash at the same 1M-token context.…
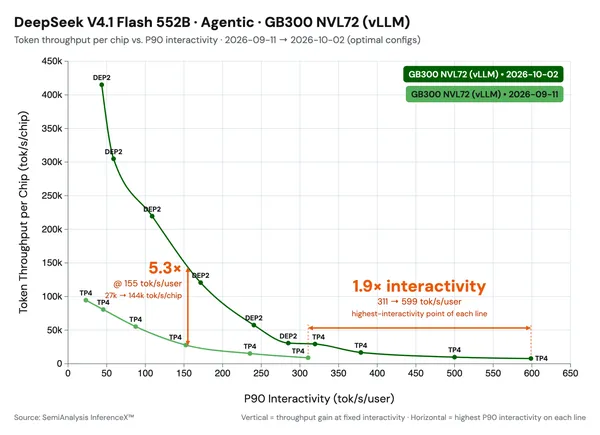
vLLM Gets DeepSeek-V4.1-Flash to 5.3x Throughput in Three Weeks
Inferact and the vLLM community say they have sped up DeepSeek-V4.1-Flash by 1.9x at low concurrency and raised throughput 5.3x under a 150 TPS constraint, within three…
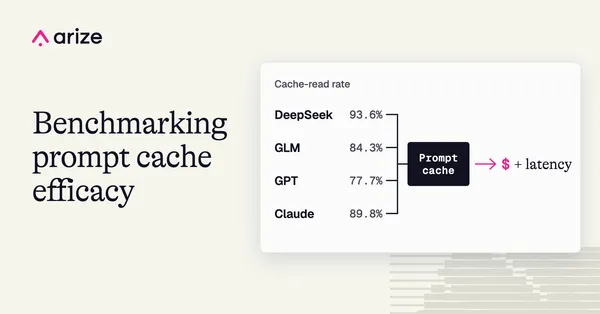
Arize benchmark: high prompt cache reuse does not guarantee lower agent cost
A prompt caching benchmark from Arize AI finds that a high cache-read rate does not always translate into lower cost. Claude Opus 5.5 read 89.8% of its prompt tokens…
Baseten Claims Fastest GLM-5 Speeds on Artificial Analysis Benchmark
Baseten says its Model API for GLM-5 reached more than 200 tokens per second in a benchmark by Artificial Analysis, with a time to first token of roughly 200ms.…
Australian MP urges public input on AI's role in youth radicalisation
Senator Raff Ciccone, chair of Australia's Parliamentary Joint Committee on Intelligence and Security, is calling on parents, teachers, researchers, tech platforms and…