CoreWeave Outlines How Its AI Data Centers Tackle Power, Scale and Uptime
CoreWeave has published its capacity plans for its data centers, arguing that purpose-built, liquid-cooled facilities are needed to meet the demands of AI megaclusters. The company names four challenges it says shape the AI landscape in 2025 and beyond, and describes how it addresses each.
- CoreWeave names four challenges: rack power, traditional data center limits, maximum performance and burstable compute.
- The company expects most of its data centers opening in 2025 to have liquid cooling and says its designs support ~130kW racks.
- CoreWeave says typical co-location sites usually support only 5 to 10 kW positions.
- Its performance stack includes LOTA storage, NVIDIA Quantum-2 InfiniBand networking and Mission Control node lifecycle tools.
- CoreWeave says it offers the broadest selection of the highest performance NVIDIA GPUs for burstable demand.
Rising rack power and the case for liquid cooling
CoreWeave says the shift from distributed computing setups to megaclusters with hundreds or thousands of GPUs in a single fabric is raising power demand sharply. Its first challenge is increased rack power consumption. The company points to NVIDIA Blackwell, noting that the NVIDIA GB200 NVL72 has 72 GPUs in a single rack and delivers up to 30-times faster real-time trillion-parameter inference.
Higher performance means more power and hotter chips, according to CoreWeave. It says typical co-location sites usually support only 5 to 10 kW positions, which makes traditional rack builds unable to keep up. The company also states that air cooling alone cannot effectively cool these GPUs, and that racks need up to four times more power.
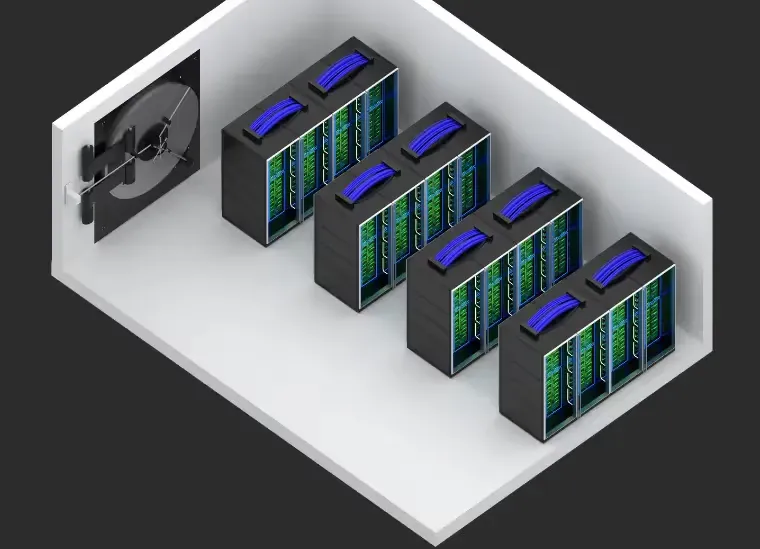
CoreWeave says it expects most of its data centers opening in 2025 to have liquid cooling capabilities. Rather than carving out small portions of a facility to add liquid cooling later, it designs entire data centers around it, which it says enables support for ~130kW racks. The company says it can iterate on this base design and repeat it across locations to offer customers a fast time-to-market.
Beyond traditional designs: partnerships, security and performance
The second challenge is the lack of support from traditional data center designs. CoreWeave argues that facilities built for CPU workloads are not equipped for GPU megaclusters of 100,000+ GPUs with 100s of megawatts of power. Its answer is purpose-built AI facilities and close ties with hardware and data center vendors. The company says it can co-design critical components of the infrastructure, works hands-on with partners to improve manufacturing and testing so later batches see fewer issues, and collaborates with NVIDIA. According to CoreWeave, this means customers will not have to wait for costly retrofits.
On security, the company says all its data centers are limited-access buildings with no visible signage, with around-the-clock security personnel. It also cites air-tight entry protocols and internal data and IP safeguarding to support identity access management and least-privileged access.
The third challenge is getting maximum performance. CoreWeave cites the 2024 Llama 3 Report, which found that models can experience up to 420 unexpected interruptions over a 54-day period. The paper noted that "a single GPU failure may require a restart of the entire job," according to the quote reproduced by CoreWeave. The company says such breakdowns bring time-consuming interruptions and unnecessary costs.
To address this, CoreWeave points to three parts of its platform:
- Storage: CoreWeave Local Object Transport Accelerator (LOTA), a proxy on GPU nodes that gives a more direct path between GPUs and data.
- Networking: NVIDIA Quantum-2 InfiniBand-based cluster networks with a SHARP-enabled network for multi-node interconnect.
- Mission Control: Fleet Lifecycle Controller and Node Lifecycle Controller, which automate node provisioning, testing and monitoring, and swap out nodes that underperform even slightly.
Burstable compute and what it means for AI teams
The fourth challenge is access to burstable compute. Not all workloads need the same amount of compute, CoreWeave says, and GPUs are in ultra-high demand, so supply is often limited. The company says customers can go from completely quiet periods to tens of megawatts of power usage within minutes when a training run starts.
CoreWeave states that it offers the broadest selection of the highest performance NVIDIA GPUs, and that this lets it provide buffer capacity and engineering support to keep large, complex clusters stable. It adds that its data center build-out planning takes backup power into account. The source text is cut off at this point, so further detail on that point is not available.
For AI enterprises choosing an infrastructure provider, the post sets out what CoreWeave considers the main criteria: power density, facilities designed for GPU scale, cluster resilience and access to varied GPU capacity. All performance and capacity claims in the post are the company's own, and the source does not give pricing, site locations or specific capacity figures for individual data centers.
CoreWeave: Our Capacity Plans for CoreWeave Data Centers